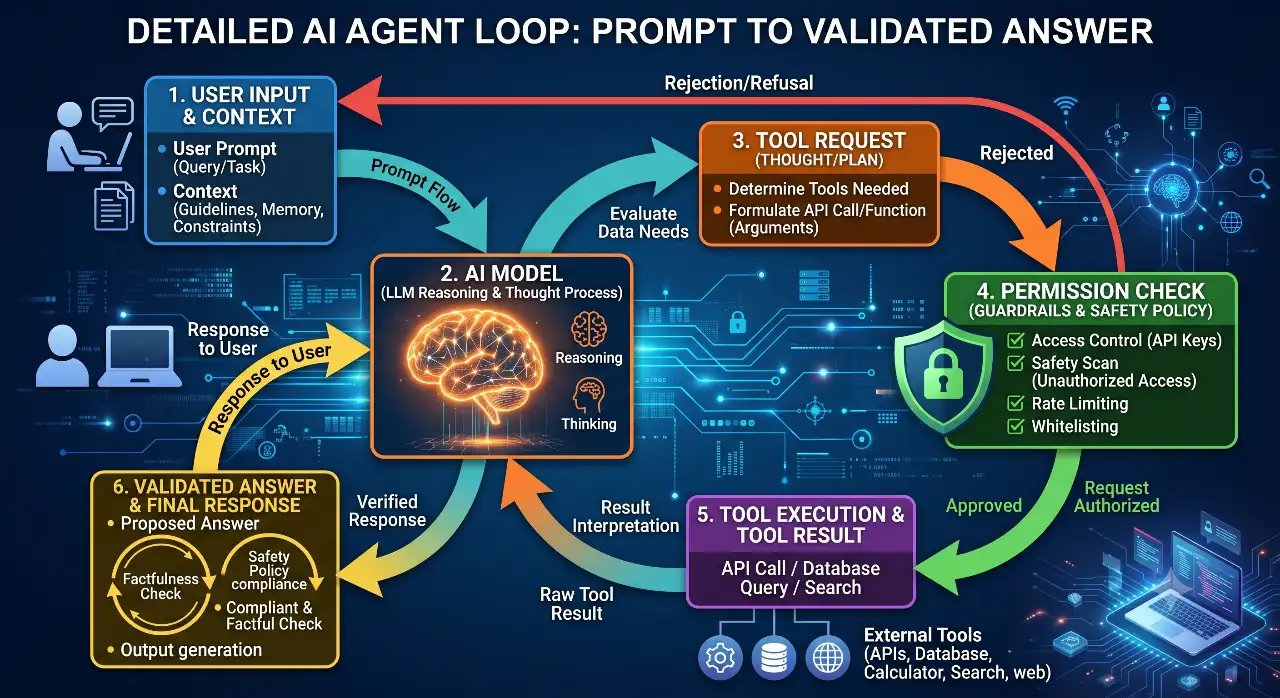
OpenAI AI is more than a search phrase. It describes a family of generative and reasoning technologies that process instructions and context to produce text, analyze images, use tools, and support software workflows. This guide approaches the subject from a practical decision-making perspective: what it is, how it works, and where it creates measurable value.
This long-form guide is written for curious readers, technology students, product teams, and developers who want a non-hyped explanation of modern AI systems. It explains the core concepts, architecture, practical use cases, selection criteria, security concerns, implementation steps, and future direction without assuming that one platform is automatically best for every workload.
Quick answer: OpenAI AI systems receive instructions and context, use a selected model to generate or reason, optionally call approved tools, and return output that the application must validate and present responsibly.
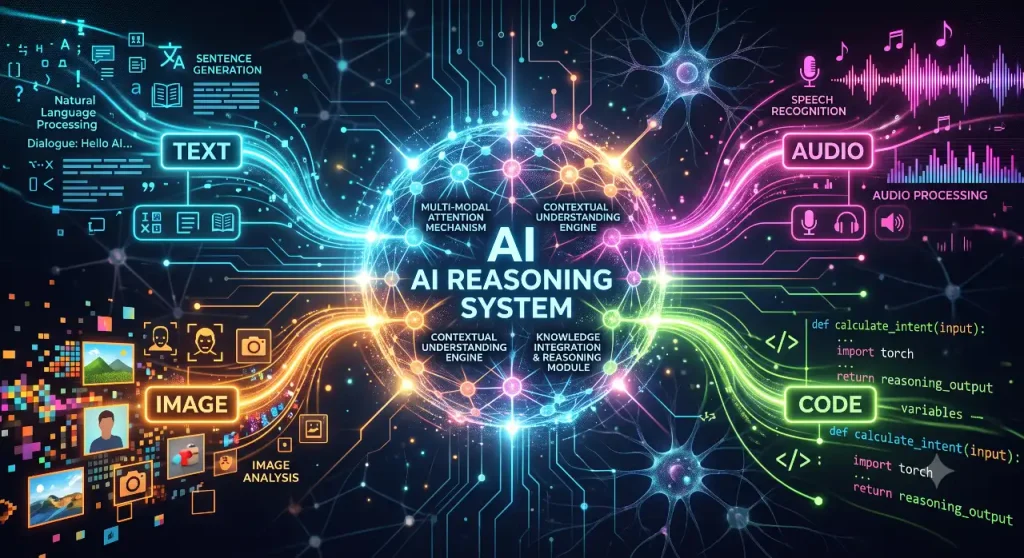
What does OpenAI AI mean?
The phrase OpenAI AI describes model capabilities and the surrounding software that turns those capabilities into a usable product or application. In practice, the phrase covers a chain of decisions: the interface a user sees, the model that interprets a request, the data supplied as context, any tools the model can call, and the controls that decide what is allowed.
Understanding the boundary between the model and the application prevents two common errors: attributing every product feature to the model and assuming the model controls data or actions by itself. A strong explanation therefore focuses on outcomes and operational responsibilities rather than describing AI as an independent digital mind. Models generate outputs from inputs and learned patterns; applications must still manage identity, data access, verification, and accountability.
How OpenAI AI systems works
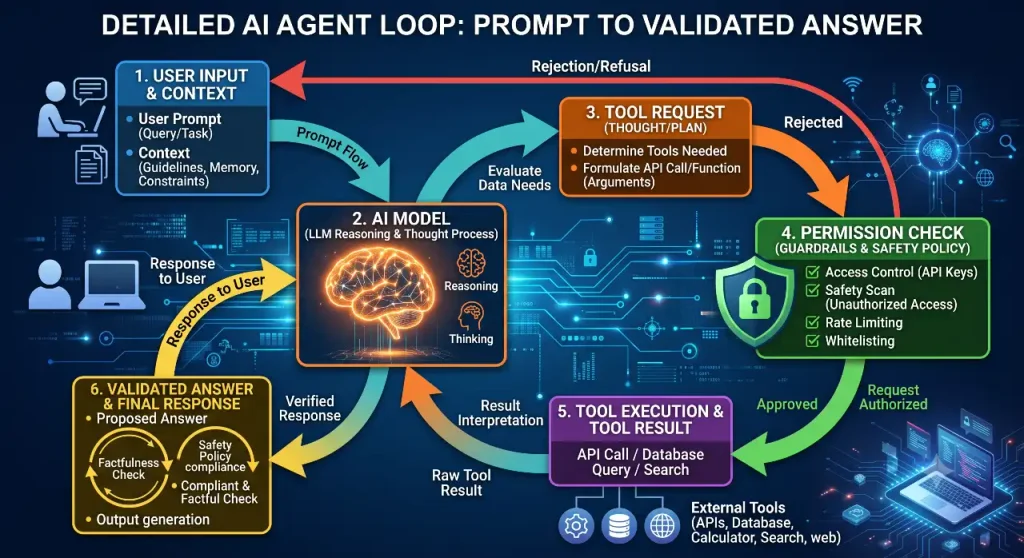
For OpenAI AI systems, production quality comes from the complete data path—input, model, tools, validation, logging, and controlled output. A request normally moves from a user or application into an API or product interface. The system may add instructions, retrieve approved information, call a tool, ask a model to generate or reason, validate the result, and then return an answer or action.
The model predicts useful output from the information in its active context; retrieval and tools can add current or private information, but their permissions and results are managed by the host application. The exact implementation varies, but the following layers provide a useful map.
| Layer or capability | Role in the workflow |
|---|---|
| Instructions | System and user directions that define the goal, constraints, response style, and approval boundaries. |
| Context | Conversation history, documents, images, tool results, and other information available for the current task. |
| Model | The selected model family and reasoning configuration that interprets input and generates output. |
| Retrieval | A controlled method for finding relevant passages from approved files or knowledge stores. |
| Tools | Search, code, computer, or custom functions the application allows the model to request. |
| Validation | Automated checks, evaluations, moderation, citations, and human review before a result is trusted or acted upon. |
Where OpenAI AI creates practical value
The best use cases for OpenAI AI systems have a clear input, a reviewable output, and a measurable benefit. They also tolerate the remaining uncertainty of probabilistic models or add deterministic checks where mistakes would be costly.
- Explain complex material at different reading levels while teachers or experts review accuracy and pedagogy.
- Convert unstructured documents into structured fields with schema validation and exception handling.
- Generate drafts, alternatives, outlines, and critiques without treating generated text as a final source of truth.
- Assist analysts by summarizing evidence and identifying questions that still require primary-source investigation.
- Support software tasks by reading code context, proposing changes, running permitted tools, and reporting test results.
When piloting OpenAI AI systems, start with one workflow that has enough volume to matter but is not so critical that an early error creates irreversible harm. This makes it possible to learn about prompt quality, tool reliability, user behavior, and support needs before expanding the deployment.
A step-by-step implementation workflow
- Step 1: Describe the real task, decision owner, and consequence of a wrong result.
- Step 2: Prepare representative inputs and an evaluation rubric before selecting a model.
- Step 3: Provide concise instructions and the minimum authoritative context needed for the task.
- Step 4: Add retrieval or tools only when they measurably improve accuracy or enable a required action.
- Step 5: Validate output structure, factual support, safety, and tool side effects before presenting the result.
- Step 6: Monitor production examples and update prompts, data, or controls through a documented review process.
Document the result of each step for OpenAI AI systems. The goal is not simply to launch a feature; it is to create a repeatable process for deciding whether the workflow is ready, what may be automated, and where a person must remain responsible.
Architecture, data, and tool orchestration
A useful mental model is a loop: instructions and context enter, the model returns text or a tool request, the application executes only permitted operations, and the model uses returned evidence to complete the response. Retrieval should use curated sources, tool definitions should be narrow and explicit, and every side-effecting action should have appropriate authentication and approval. A model can decide that a tool is useful, but the surrounding application must enforce what the tool is permitted to do.
Long context can be valuable in OpenAI AI systems, yet sending more information is not always better. Irrelevant documents increase cost and can distract the model. A better pattern is to retrieve the smallest authoritative context, preserve source metadata, and evaluate whether the answer is supported by that evidence.
Security, privacy, and governance
Governance for OpenAI AI systems should be designed with the workflow, not added after launch. Classify the data, identify the accountable owner, define prohibited uses, and decide when human approval is mandatory. Never place passwords, private keys, payment credentials, or unrestricted personal data in prompts or logs.
- Hallucination or fabricated detail when the model lacks evidence but is still asked to answer confidently.
- Prompt injection inside retrieved pages or files attempting to override trusted application instructions.
- Automation bias when users accept a well-written answer without checking its source, assumptions, or uncertainty.
- Data leakage through excessive context, unsafe logs, broad connectors, or poorly isolated user sessions.
- Evaluation gaps that hide failures affecting languages, edge cases, or groups underrepresented in the test set.
Security around OpenAI AI systems should use least-privilege access for people, service accounts, connectors, and function calls. Protect stored data with appropriate encryption and retention controls. Keep an audit trail for high-impact actions, but avoid logging sensitive content that the team does not need. Review the whole application—not only the model provider.
Cost, performance, and platform selection
When selecting technology for OpenAI AI systems, a feature list is only a starting point; representative tests should decide which option belongs in production. Evaluate at least quality, latency, context behavior, tool support, reliability, safety, regional availability, and total cost. A premium model can be economical when it prevents expensive corrections; a smaller model can be the better choice when the task is narrow and high-volume.
Model capability matters, but context quality and evaluation design often determine whether the system works. Test the complete workflow instead of ranking models with unrelated benchmarks. Build a small evaluation set from real requests, include difficult and adversarial cases, and score results with explicit criteria. Repeat the evaluation when the model, prompt, retrieval corpus, or tool definitions change.
Capacity planning for OpenAI AI systems should include rate limits, peak concurrency, large file handling, streaming, retries, and fallback behavior. Track usage by product feature or customer rather than relying only on one organization-wide bill.
Common mistakes to avoid
- Starting with OpenAI AI before defining the task, user, acceptable error rate, and business owner.
- Treating a fluent answer as verified truth instead of evaluating OpenAI AI systems on representative examples.
- Moving from a demo to production without permissions, logging, fallback behavior, or incident ownership.
- Comparing headline model capability while ignoring tool cost, data preparation, retries, and human-review time.
- Using preview or changing endpoints without a version policy, regression tests, and a documented rollback path.
Best practices for dependable results
- Separate trusted instructions from untrusted user, web, and document content.
- Require evidence or explicit uncertainty for factual claims that affect decisions.
- Use narrow tool schemas and verify arguments server-side before execution.
- Keep a human approval gate for payments, account changes, publication, and other high-impact actions.
- Evaluate multilingual, adversarial, long-context, and tool-failure cases alongside normal examples.
Best practices for OpenAI AI systems become meaningful only when they are testable. Convert each principle into a requirement, dashboard metric, automated check, or review checklist. Assign an owner and a review date so the controls evolve with the product.
Metrics that matter
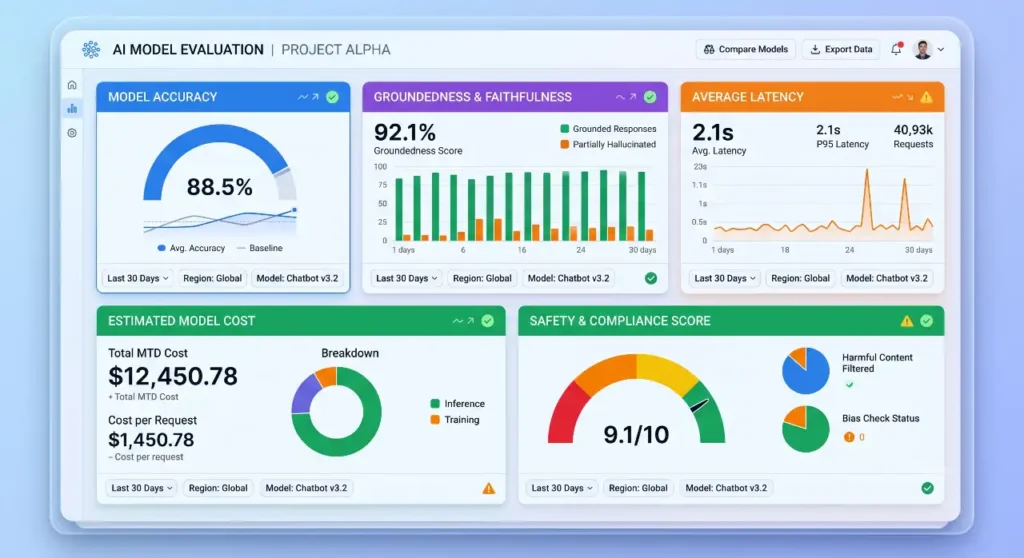
A useful dashboard for OpenAI AI systems connects technical behavior to user outcomes. The following measurement framework can be adapted to a personal project, startup, or enterprise deployment.
| Layer or capability | Role in the workflow |
|---|---|
| Task quality | Measure whether OpenAI AI systems completes the intended job against a reviewed answer set or business acceptance rule. |
| Grounded accuracy | Track unsupported claims, citation quality, retrieval success, and the rate of answers that require correction. |
| Latency | Measure typical and worst-case response time, including tool calls, network delay, retries, and moderation. |
| Total cost | Include model usage, storage, retrieval, orchestration, monitoring, engineering, and human review—not token price alone. |
| Safety and reliability | Monitor blocked requests, policy violations, sensitive-data exposure, tool failures, and successful fallback behavior. |
| User outcome | Measure adoption, completion, satisfaction, escalation rate, and the real time saved by OpenAI AI. |
Questions to ask before choosing a service
- Which model or service version powers the proposed OpenAI AI workflow, and how are version changes announced?
- What data is stored, for how long, in which region, and for what product-improvement or safety purpose?
- Which built-in and custom tools are supported, and how are permissions, approvals, and tool results recorded?
- What rate limits, context limits, output limits, availability terms, and support channels apply to this exact account?
- Can the team export prompts, evaluations, logs, files, and configuration in a usable format if the architecture changes?
- How will cost be estimated and monitored when usage, context length, tool calls, or multimodal inputs increase?
The future of OpenAI AI
OpenAI AI systems are moving toward more efficient reasoning, coordinated tool use, multimodal input, and agentic workflows, while successful deployments are becoming more evaluation-driven. The durable trend is a move from isolated chat responses toward systems that combine multimodal models, tools, private data, evaluation, and controlled action. At the same time, buyers are demanding clearer cost, governance, and reliability.
Because the technology supporting OpenAI AI systems changes quickly, avoid building a strategy around one temporary model name. Preserve portable data, use documented interfaces, maintain evaluation sets, and keep the application architecture modular enough to test another model or service when requirements change.
Final verdict
OpenAI AI can be powerful, but dependable results come from the full engineered system. Clear instructions, relevant context, constrained tools, and evidence-based review matter as much as model choice. For most readers, the smartest next step is a focused pilot with clear success criteria and non-sensitive data. Learn from the results, strengthen controls, and expand only when the workflow proves useful and dependable.
Editorial freshness note for “OpenAI AI Explained: How the Models, Data, and Tools Work”: Product names, model availability, preview status, limits, and prices can change. This article uses an official documentation snapshot reviewed on August 31, 2026. Verify the linked sources before publication and schedule periodic updates.
Official sources and further reading
Frequently Asked Questions
What is OpenAI AI in simple terms?
OpenAI AI systems receive instructions and context, use a selected model to generate or reason, optionally call approved tools, and return output that the application must validate and present responsibly.
Who should use OpenAI AI?
It is relevant to curious readers, technology students, product teams, and developers who want a non-hyped explanation of modern AI systems. The best starting point is a narrow, measurable workflow with clear review and privacy rules.
What is the most important part of OpenAI AI systems?
The complete system matters, but Instructions should be evaluated together with data quality, tools, permissions, monitoring, and human responsibility.
How should a team evaluate OpenAI AI?
Use representative tasks, an agreed answer or acceptance rubric, and measurements for quality, latency, cost, safety, and user outcome. Repeat the evaluation after important changes.
Is OpenAI AI safe for sensitive data?
Safety depends on the service terms, account configuration, data flow, retention controls, access permissions, and the application around the model. Classify data and obtain appropriate security and legal review before using sensitive information.